EPOCH IDLE
Train the network. Gradient descent, automated.
An idle game about the real loop of machine learning - scaled down, sped up, and made tactile. Start with a single scalar perceptron and straight-line data; end routing multi-head attention over tangled datasets and shifting your paradigm to the Transformer. Every purchase runs actual gradient descent. Every number on screen is live math, not a counter with a skin.
The math is the game
THE LOOP
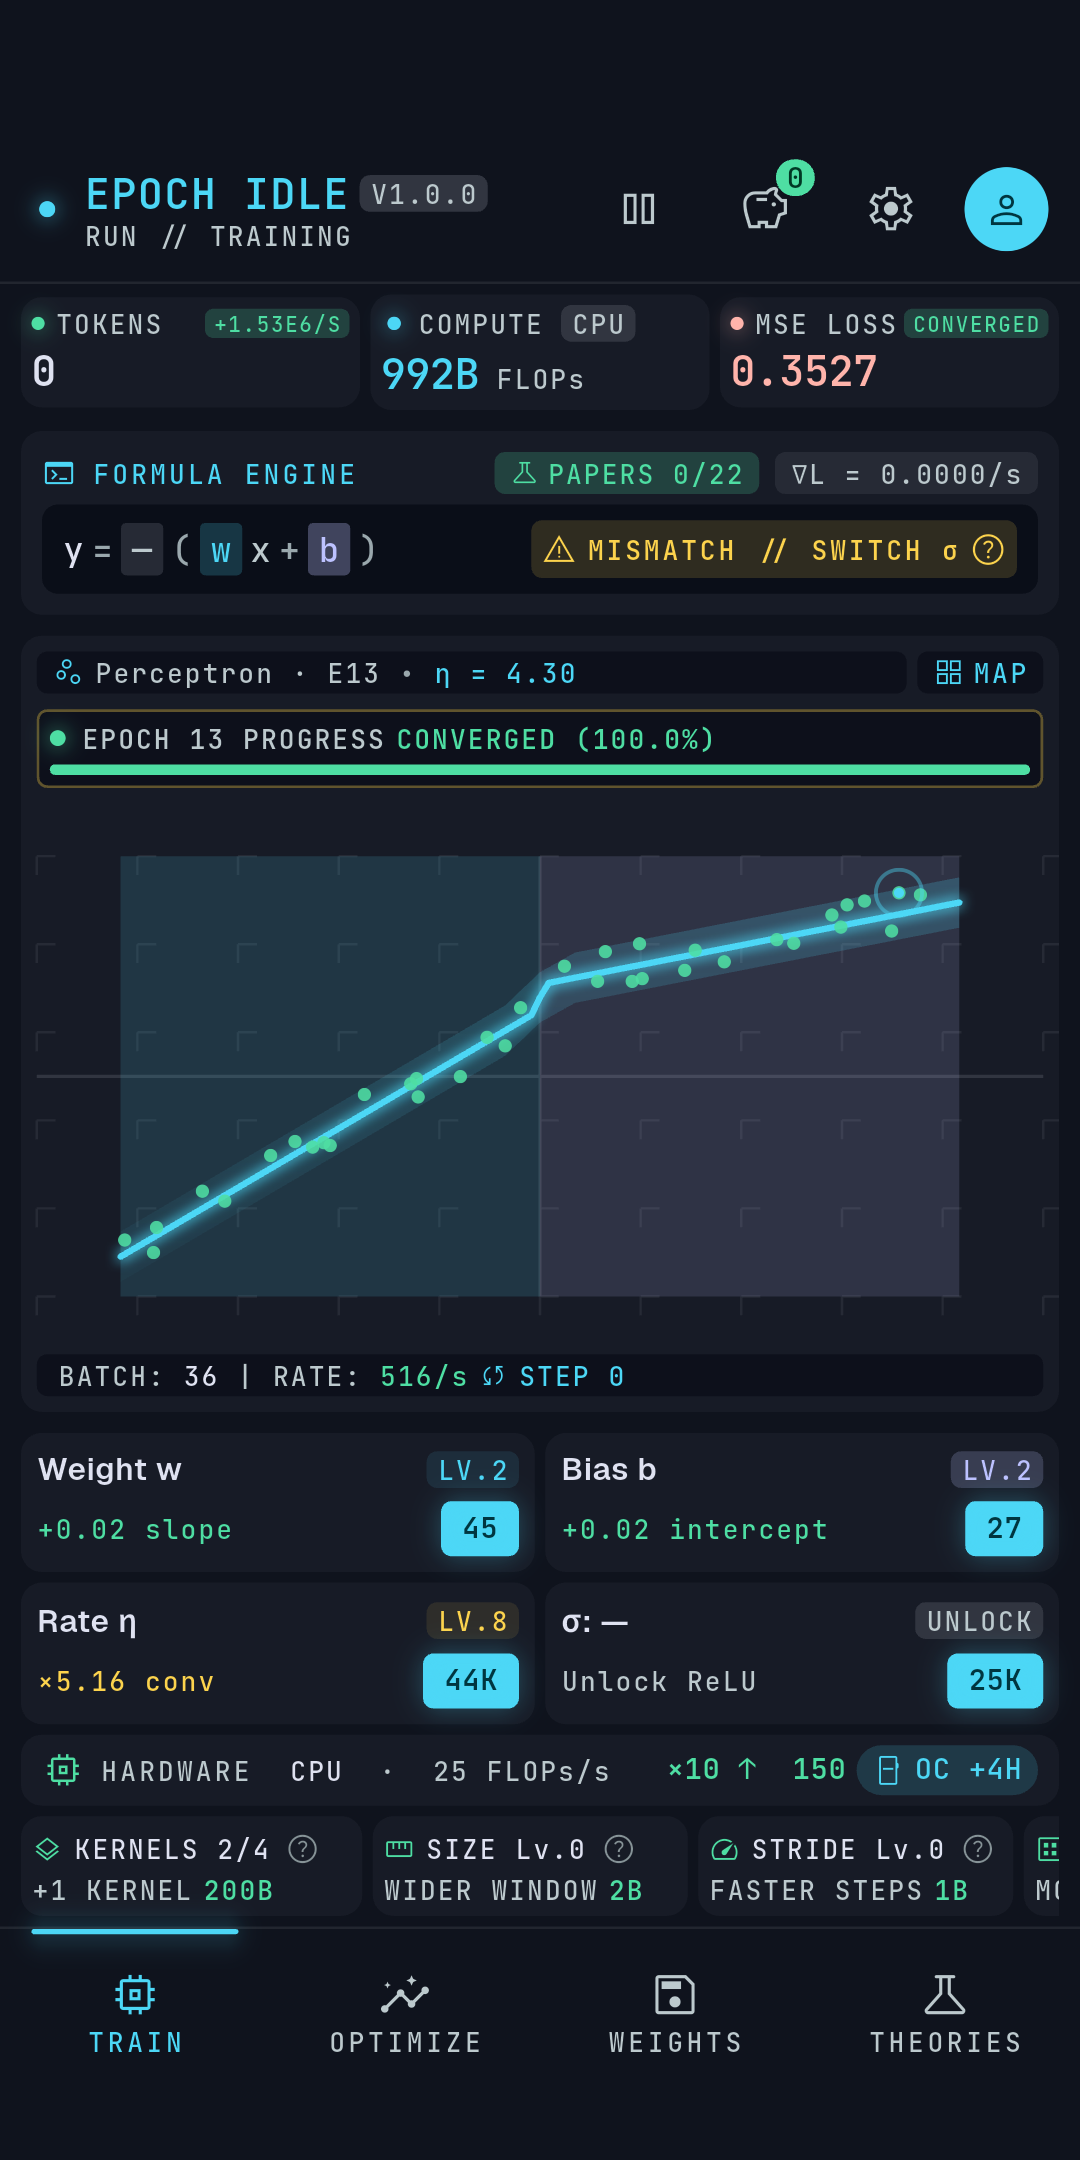
Compute buys parameters; parameters cut the loss; the loss sets your training speed. Tune weights, learning rate η, and hardware - and watch the loss curve bend in real time.
THREE DEEP
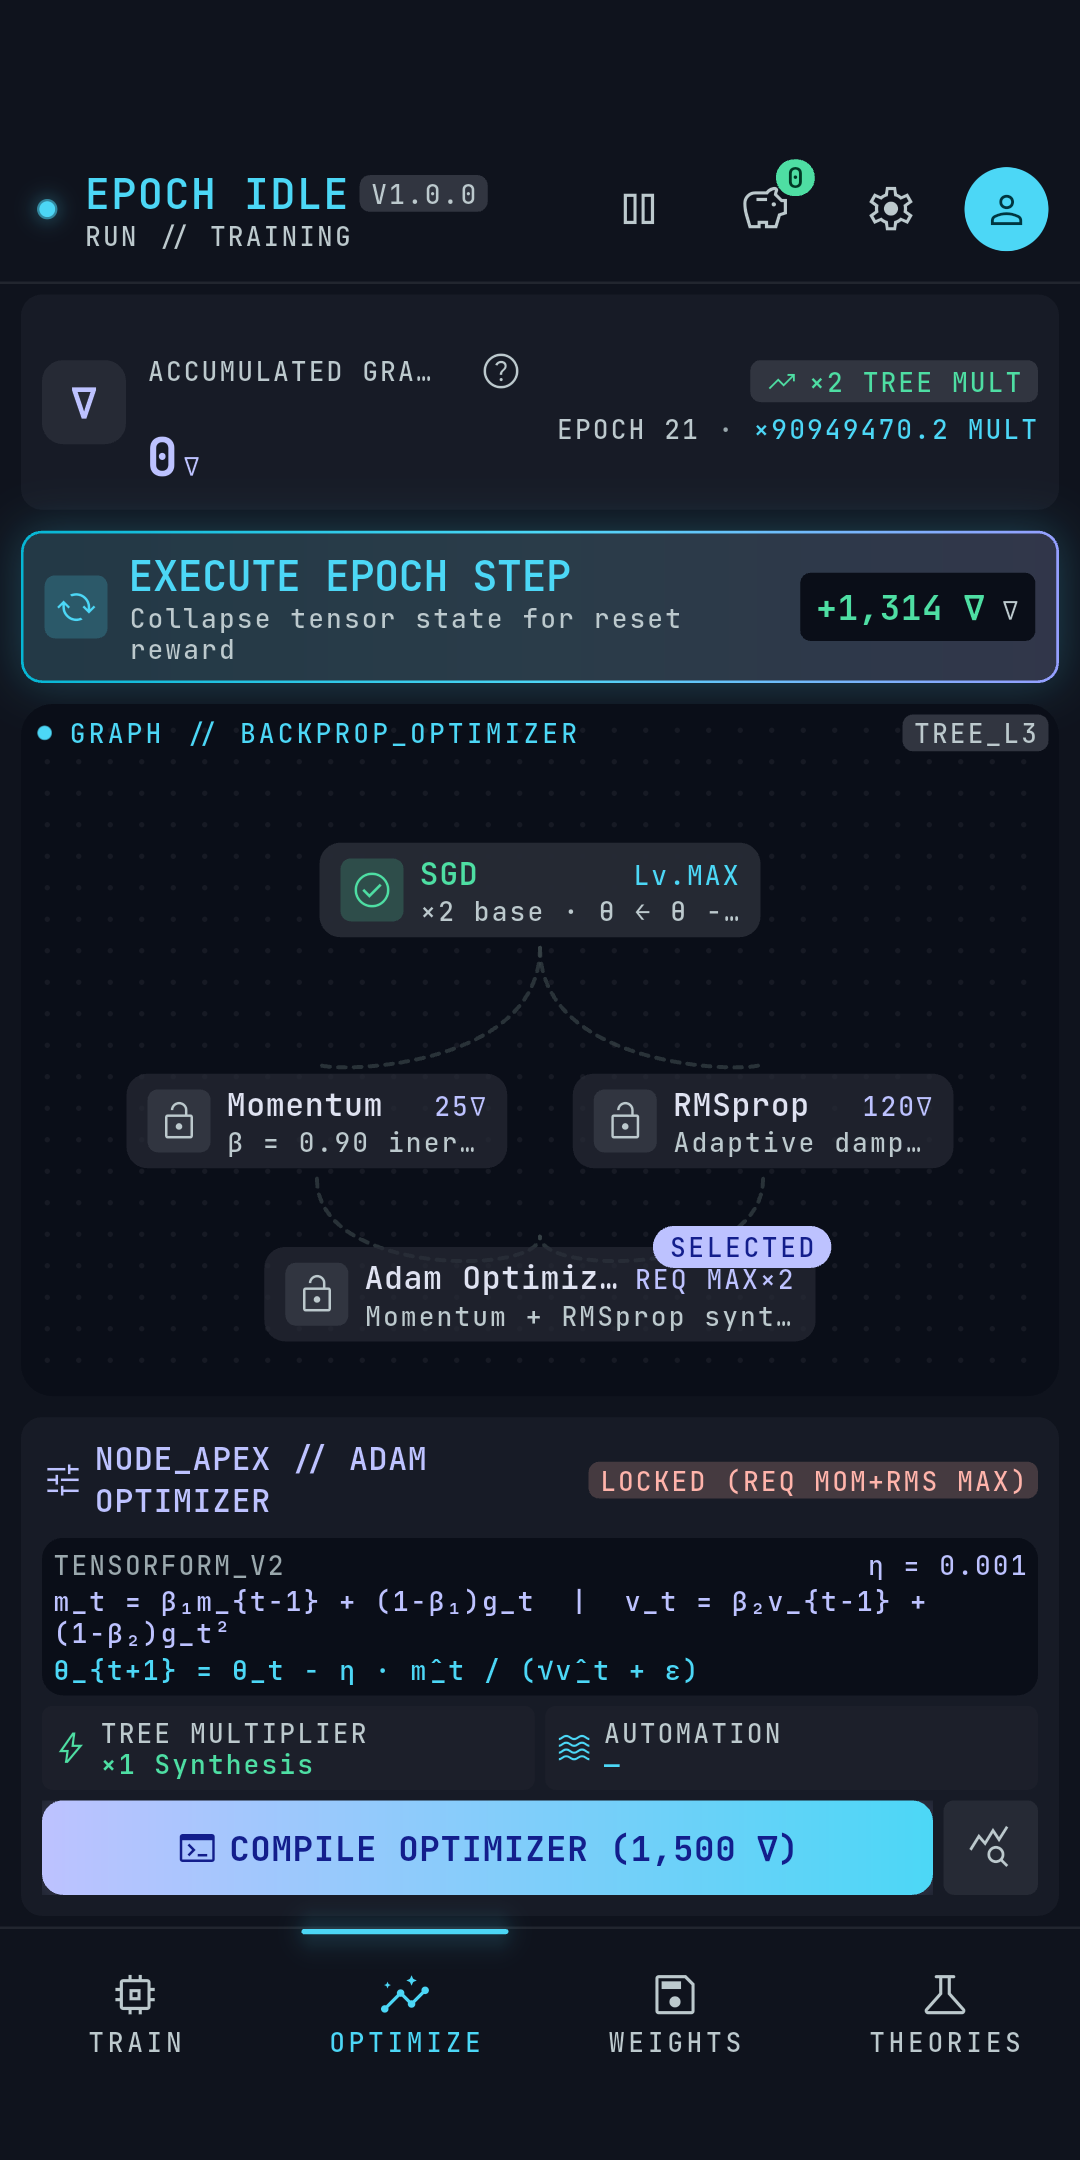
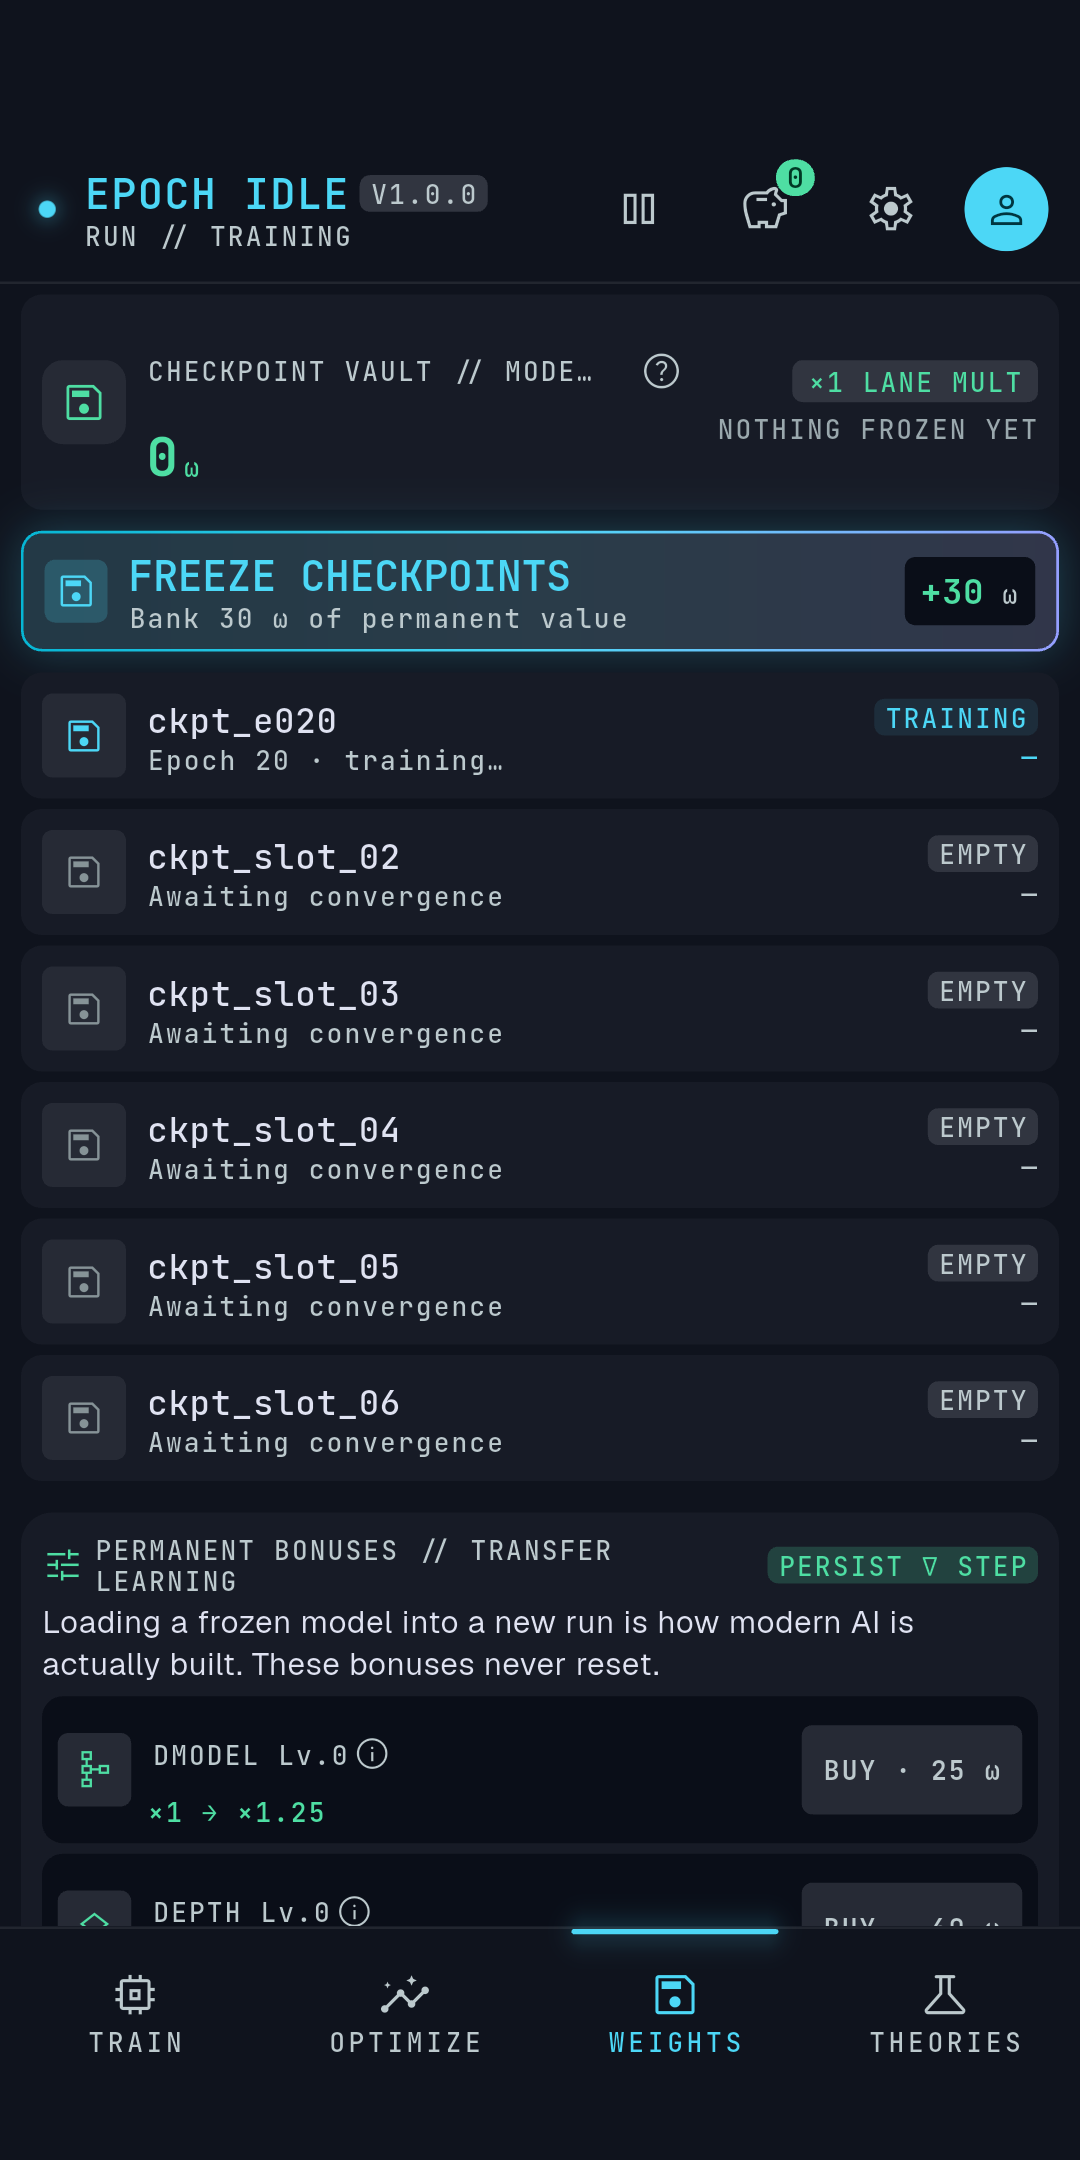
Collapse runs into ∇ gradients and spend them down the SGD → Adam optimizer tree, bank mastered datasets as permanent Model Weights ω, then reroute everything in the one-way Transformer paradigm shift.
LEARN REAL ML
32 publishable papers arrive with their real abstracts - from the perceptron to “Attention Is All You Need” - and a 37-entry concept codex explains the math behind every system you touch.
BROWSE THE CODEX →RESPECT THE PLAYER
Zero forced ads; one optional rewarded boost. Offline catch-up up to 24 h, extendable. No accounts, no cloud, no tracking - your run is a local file you can export from Settings.
Run gradient descent in 15 seconds
Drag weight w and bias b, or click STEP −∇L to fit the noisy samples. Switch to DATASET E3 (HINGE) to see why a straight line hits a ceiling until you unlock ReLU.
Live screens, live math
Learn ML through the game's mechanics
New to machine learning? These five field notes explain the real math behind every wall you hit in Epoch Idle - without burying you in linear algebra.
ONE LINE TO TRANSFORMER
How four mathematical walls pushed AI from a 1958 scalar perceptron to a Sparse Mixture-of-Experts Transformer.
READ NOTE →WHY STRAIGHT LINES FAIL
Why stacking linear layers collapses to one line, and how ReLU, Sigmoid, and GELU bend the curve.
READ NOTE →OVERFITTING & VAL GAP
Why adding parameters to a small dataset hurts test accuracy, how the 2σ²/N tax works, and why Chinchilla changed LLM scaling.
READ NOTE →OPTIMIZERS & ATTENTION
How SGD, Momentum, and Adam navigate narrow canyons, and why Multi-Head Attention replaced local convolutions.
ALL 5 FIELD NOTES →Fair questions
Does it need internet?
No - the game runs fully offline and your save stays on your device. The optional rewarded ad and purchases need a connection when you use them.
What does it cost?
Free. Optional purchases include Funding packs and two one-time unlocks (the Ad-Free Pass and the Full Research Grant). There are no forced ads, ever.
Do I need to know machine learning?
No. Everything is explained in-game - the concept codex teaches the real math as you meet it, and every paper arrives with its real abstract. You can also read our Beginner ML Field Guide right here on the site.
What languages?
English, Japanese, Korean, and Simplified or Traditional Chinese - auto-detected from your device and switchable in Settings.
Which platforms?
Android and iOS - out now. The badges up top link both stores.